Commitollama 🦙
A free alternative to Github Copilot's commit generator that runs on your device using Ollama.
Features
- No telemetry or tracking.
- No API key needed.
- Use any model you have already pulled in Ollama.
- No Internet connection needed.
- Quick model switching from the Source Control toolbar or Command Palette.
- Background pre-generation of change summaries for faster commits.
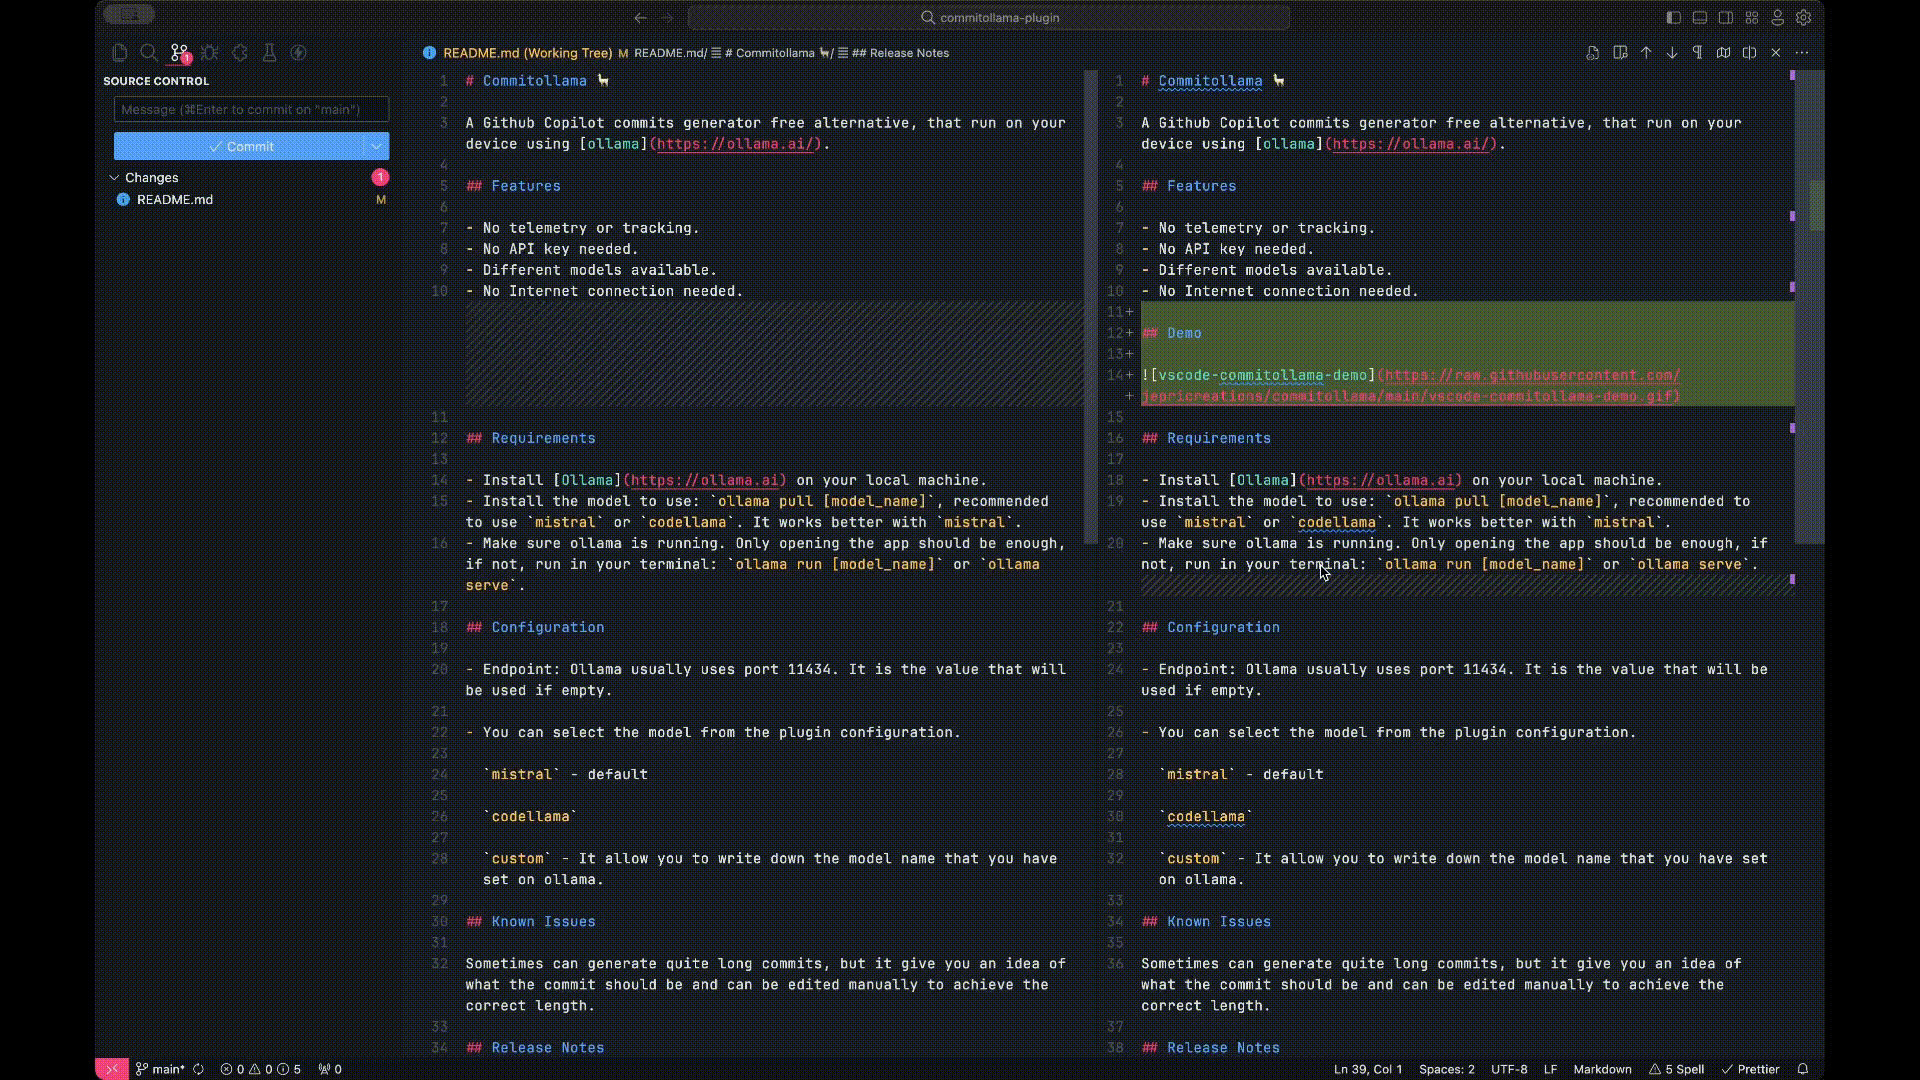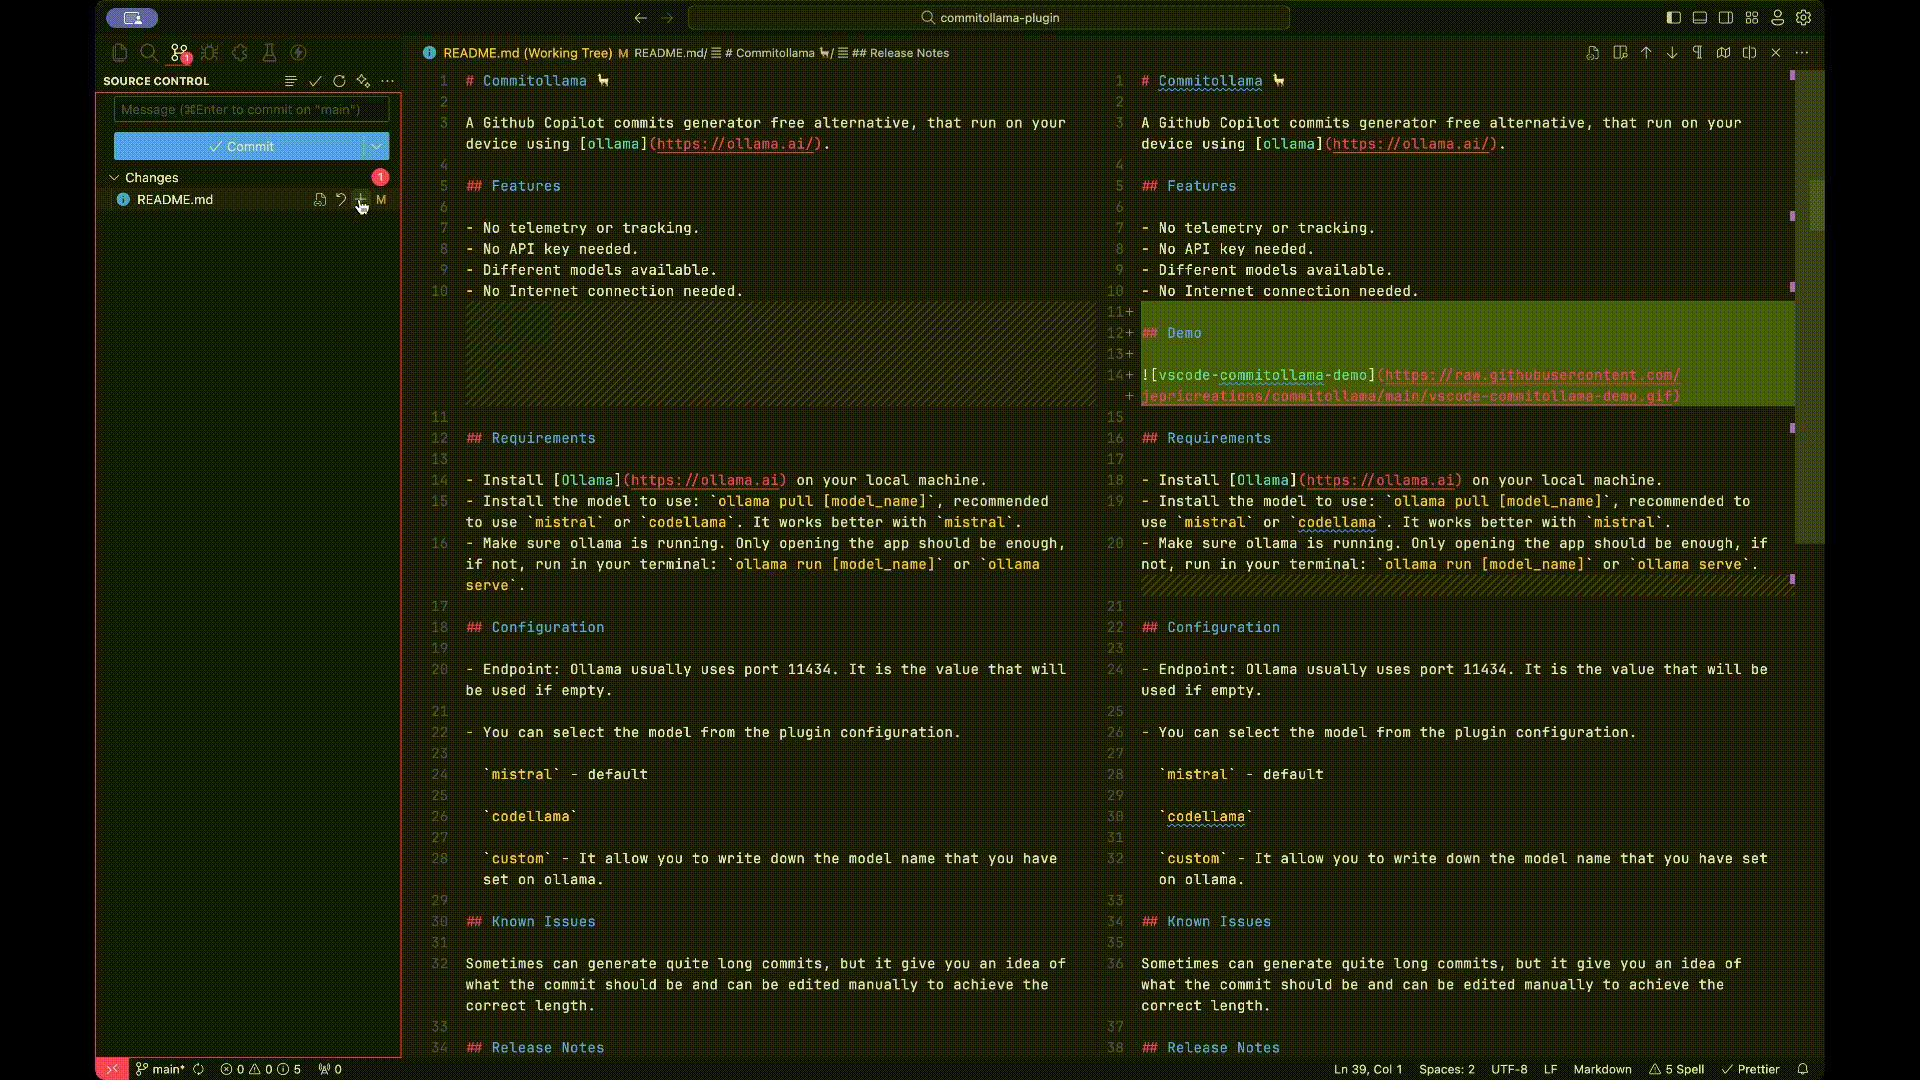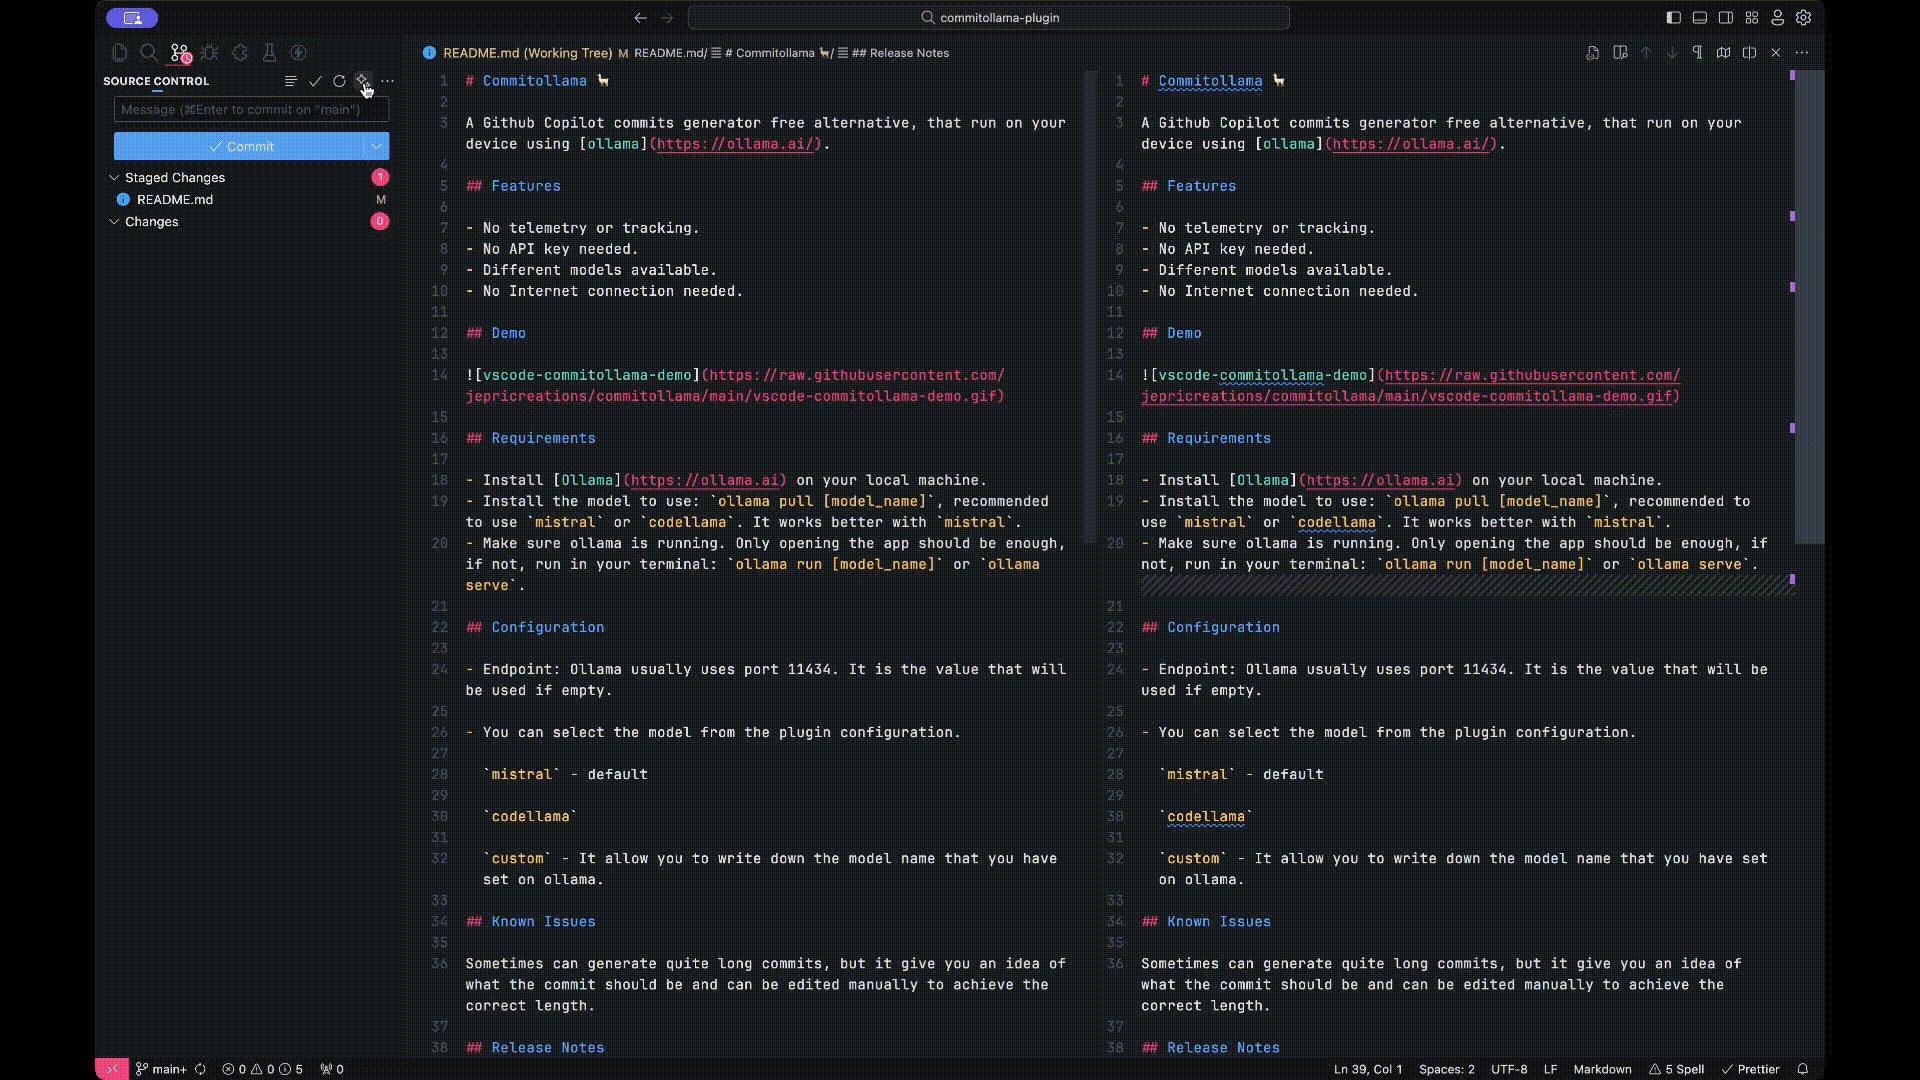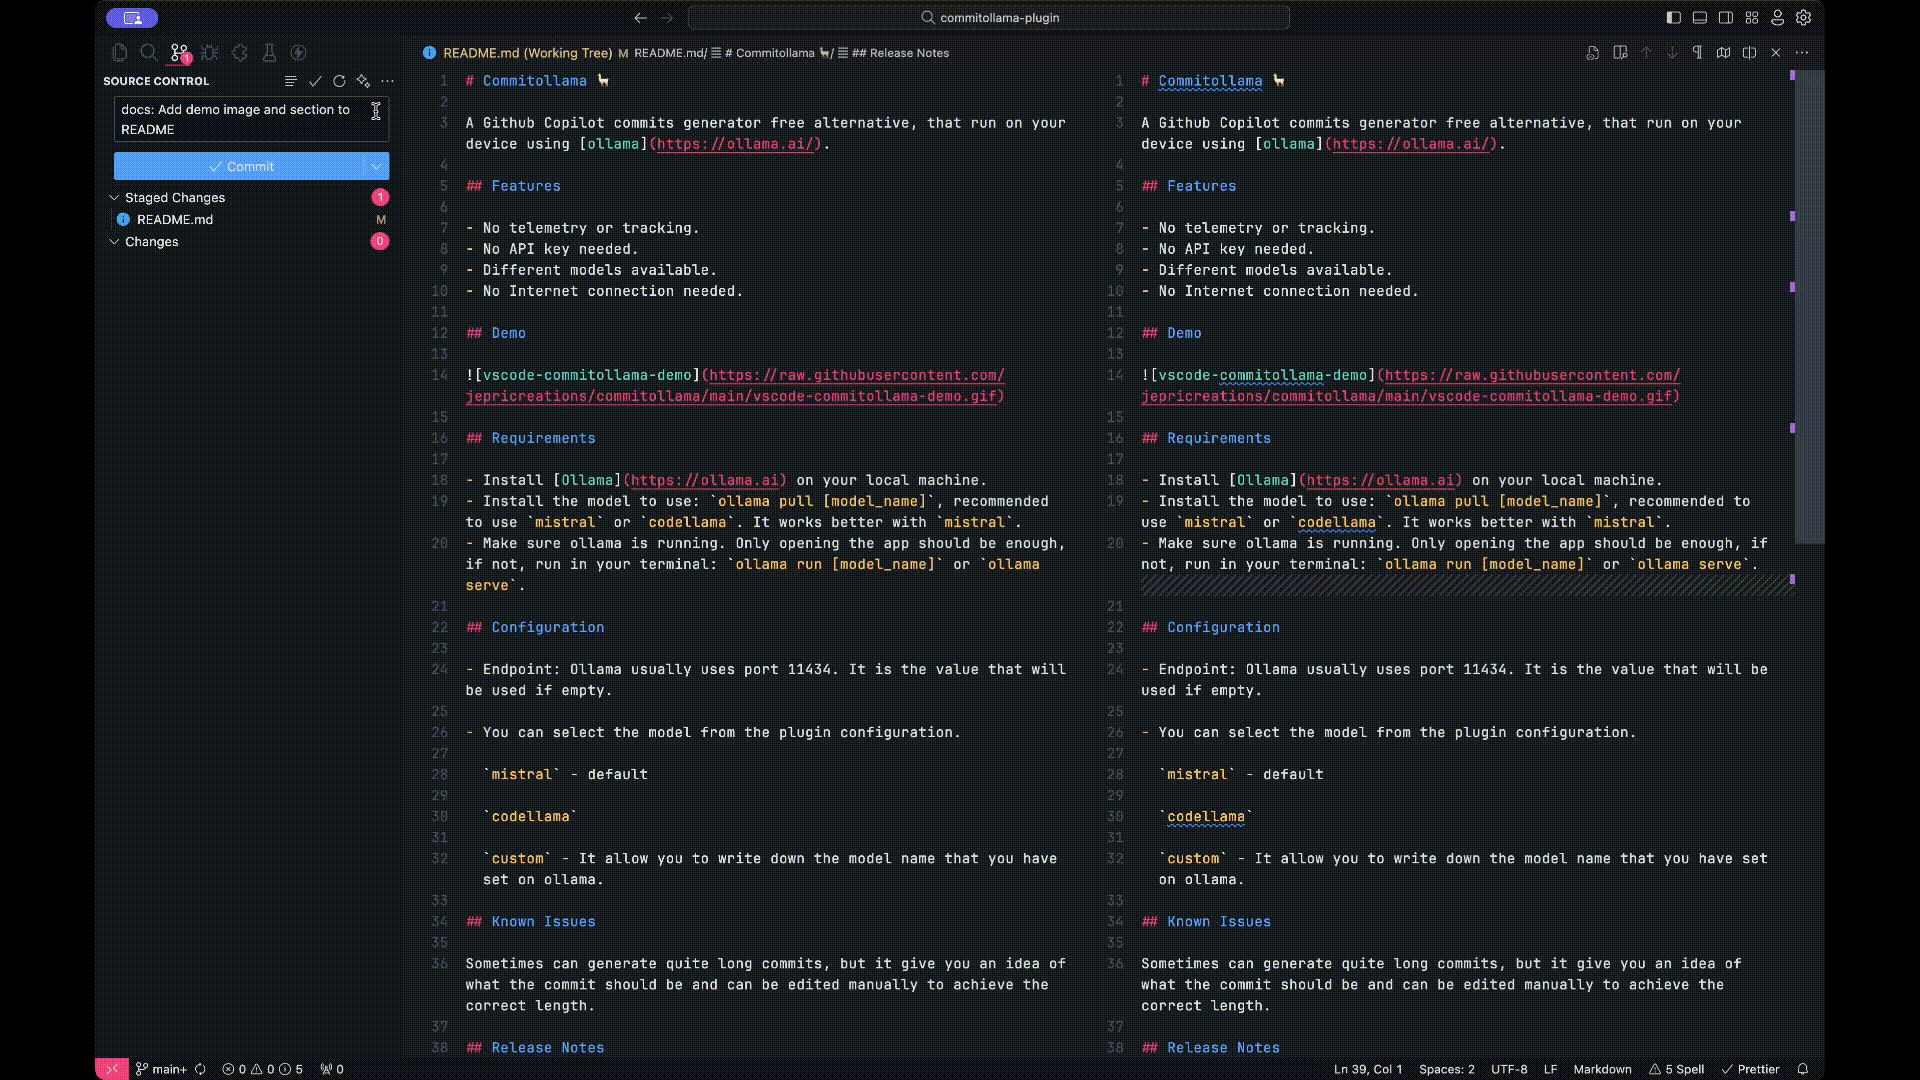
Demo
Requirements
- Install Ollama on your local machine.
- Pull at least one model, for example:
ollama pull llama3.2
- Make sure Ollama is running. Open http://127.0.0.1:11434/ in your browser (your port may differ), open the Ollama app, or run
ollama serve.
Recommended models
Prefer small, non-reasoning (no thinking) instruct/coder models. Commit messages are short tasks; thinking/reasoning models (R1, QwQ, “bonsai”, and similar) are usually much slower and often worse for this use case. In LM Studio, turn Reasoning / Thinking Off for the loaded model when that option exists.
A strong default on both Ollama and LM Studio is Qwen2.5-Coder 3B Instruct (qwen2.5-coder:3b in Ollama).
Other models that work well and are highlighted in the Ollama model picker:
llama3.2, codellama, qwen3, qwen2.5-coder:7b, mistral, gemma3, codegemma
See the Ollama library for more models.
Usage
- Stage your changes in Git.
- Run Commitollama from the Source Control title bar (sparkle icon).
- On first use, pick a model, then choose whether to save it in project settings (
.vscode/settings.json) or user settings (all projects). The picker is skipped if commitollama.model is already set in either scope.
- The generated commit message is written to the commit input box.
Switching models
Use the swap icon next to the sparkle button in Source Control, or run Commitollama: Switch Model from the Command Palette. You can change the model and where it is saved at any time.
You can also set commitollama.model manually in VS Code settings.
Configuration
General
| Setting |
Description |
Default |
commitollama.provider |
Inference provider: ollama or openai-compatible (LM Studio and similar). |
ollama |
commitollama.model |
Model id (e.g. llama3.2:latest or an LM Studio model id). Set via the model picker or manually. |
llama3.2:latest |
commitollama.promptStrategy |
auto (diff when small, otherwise summaries), diff (always one call on the staged diff), or summaries (summarize files first). |
auto |
commitollama.useEmojis |
Add emojis to commit messages. |
false |
commitollama.useDescription |
Add a longer description below the subject line. |
false |
commitollama.useLowerCase |
Lowercase the first letter of the commit message. |
false |
commitollama.language |
Language preset (English, Spanish, Custom, …). |
English |
commitollama.promptTemperature |
Model temperature (0–1). Higher = more creative. |
0.2 |
commitollama.commitTemplate |
Final commit format. Placeholders: {{type}}, {{emoji}}, {{message}}. |
{{type}} {{emoji}}: {{message}} |
Custom overrides
| Setting |
Description |
commitollama.custom.language |
Custom language. Used when commitollama.language is Custom. |
commitollama.custom.emojis |
Map commit types to emojis. Only used when emojis are enabled. |
commitollama.custom.endpoint |
Inference server URL. Empty uses the provider default (http://127.0.0.1:11434 for Ollama, http://127.0.0.1:1234/v1 for OpenAI-compatible). |
commitollama.custom.prompt |
Replace the default commit prompt entirely. |
commitollama.custom.typeRules |
Custom rules for commit types. |
commitollama.custom.commitMessageRules |
Custom rules for the commit subject. |
commitollama.custom.descriptionPrompt |
Custom prompt for the commit description. |
commitollama.custom.requestHeaders |
Extra HTTP headers for inference requests (e.g. auth). |
OpenAI-compatible servers (LM Studio, etc.)
- Start the local server and load a model.
- Set the provider and endpoint (LM Studio defaults shown):
{
  "commitollama.provider": "openai-compatible",
  "commitollama.custom.endpoint": "http://127.0.0.1:1234/v1"
}
- Run Commitollama: Switch Model and pick a model from the server.
- Use a non-thinking model (for example Qwen2.5-Coder 3B Instruct) and disable Reasoning/Thinking in LM Studio if available.
Example emoji map:
"commitollama.custom.emojis": {
  "feat": "✨",
  "fix": "🐛",
  "docs": "📝",
  "style": "💎",
  "refactor": "♻️",
  "test": "🧪",
  "chore": "📦",
  "revert": "⏪"
}
Background generation
Summarizes file changes in the background while you work. When you commit, cached summaries are reused when possible, so generation is faster.
| Setting |
Description |
Default |
commitollama.background.enabled |
Enable background generation. |
true |
commitollama.background.interval |
Seconds between periodic scans. |
60 |
commitollama.background.onSave |
Summarize when a file is saved. |
true |
Known Issues
- Depending on the model, commit messages can be longer than ideal. They are meant as a starting point and can be edited before committing.
- Some models do not support the structured JSON output Commitollama uses (for example certain reasoning or harmony-format models). Prefer a non-thinking recommended model via Commitollama: Switch Model. Error messages include the underlying provider response when available.
Contributing
- Fork the repository and create a feature branch.
- Install dependencies:
pnpm install
- Lint and format:
pnpm run lint and pnpm run format-fix
- Run tests:
pnpm test
- Build:
pnpm run build (or pnpm run watch)
- Follow the existing style and configuration (
biome.json).
- Open a PR against
main with a clear description and meaningful commits (e.g. type(scope): message).

