Nexus AI — Graph-Grounded Code Intelligence
Ask questions about your codebase in plain English. Get grounded, citation-backed answers — streamed live, right inside VS Code.
Nexus AI builds a call graph + vector index of your codebase and uses it to answer questions with full structural awareness. It doesn't just search for keywords — it understands how your code is connected, who calls what, and which files are most relevant to your question. Powered by a Graph RAG pipeline that combines semantic search, keyword search, graph traversal, and cross-encoder reranking.
100% local & private. Your code never leaves your machine. The index lives in .nexus/graph.db inside your workspace. No cloud database, no telemetry, no server to manage.
What You Can Do
| Mode |
Description |
| Explain |
Ask anything about your code — get streamed answers with clickable file and line citations. Works with any selection: functions, classes, or module-level code. |
| Debug |
Point at a function — get a ranked list of likely root causes with impact analysis across the call graph |
| Review |
Get structured findings (severity · category · suggestion) ready to post directly to a GitHub PR |
| Test |
Generate framework-aware tests written directly into your repo |
|
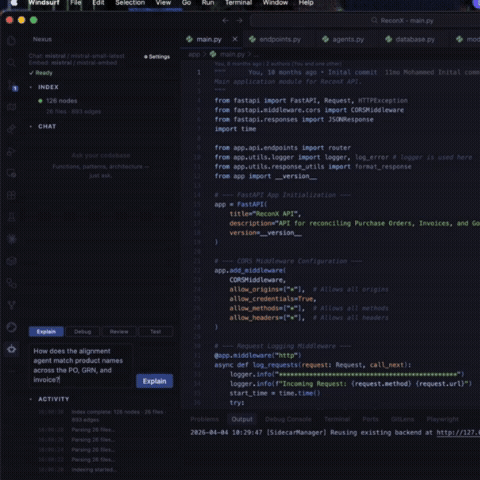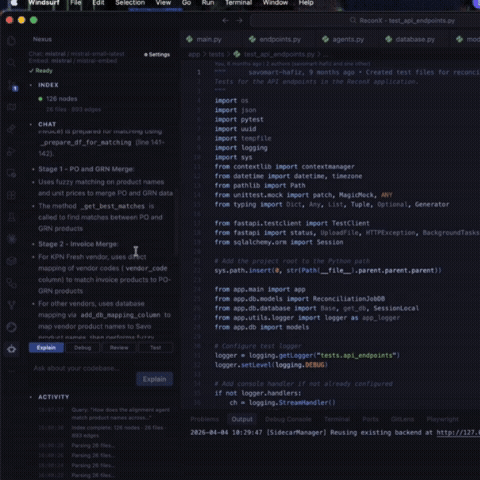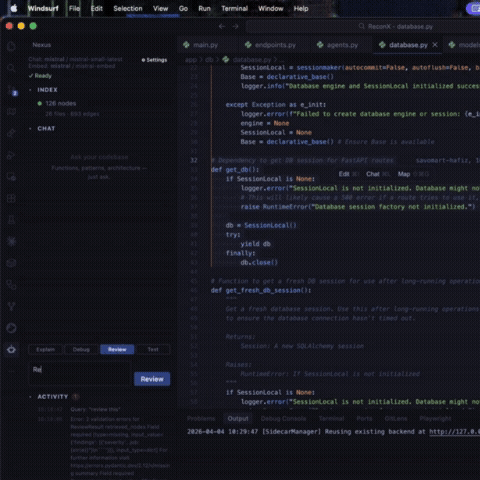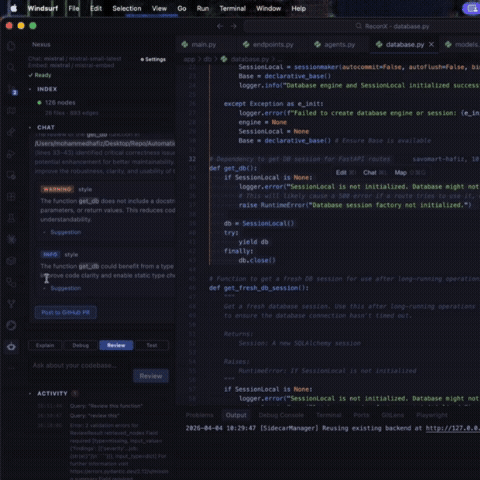
|
Features
- Graph-aware retrieval — uses Personalized PageRank to traverse the call graph and class-method relationships from matched code, surfacing structurally connected functions and the class methods that belong to them
- Dual-search pipeline — semantic vector search and BM25 keyword search run in parallel and are rank-fused, catching exact function and symbol name queries that embedding similarity alone can miss
- Full-source context — the LLM receives the complete source body of the most relevant functions, not a truncated preview, so complex implementations are answered with full information
- Diverse result selection — picks context from across your codebase rather than returning multiple methods from the same file, keeping answers grounded in the full picture
- Cross-encoder reranking — a second-pass model jointly scores each retrieved snippet against your query for higher relevance accuracy; pre-warmed at startup so the first query has no cold-start delay
- Live streaming answers — tokens stream into the chat panel as the LLM generates them
- Clickable citations — every answer links to the exact file and line number in your editor
- Incremental re-index — file saves trigger automatic background re-indexing with a 2s debounce; index stays current without manual intervention
- Embedding mismatch detection — detects when you switch embedding providers or models and blocks chat until the index is rebuilt with the new model
- Secure API key storage — keys stored in VS Code SecretStorage (OS keychain), never written to disk or
settings.json
- Multi-workspace support — each workspace gets its own isolated
.nexus/graph.db index; opening multiple workspaces never cross-contaminates results
Getting Started
1. Install
Search Nexus AI in the VS Code Extensions panel and click Install.
On first activation the extension downloads the backend binary for your platform from GitHub Releases, verifies its SHA256 checksum, and caches it permanently in VS Code's global storage. Subsequent activations use the local cache with no network call.
2. Set your API key
Cmd+Shift+P → Nexus: Setup — Configure API Key → pick your provider → paste your key.
3. Choose your provider
Code → Settings → Extensions → Nexus AI — pick chat and embedding provider and model names.
4. Index your workspace
Cmd+Shift+P → Nexus: Index Workspace
Chat unlocks once indexing completes. Your index is saved in .nexus/graph.db inside the workspace.
5. Ask a question
Click the Nexus AI icon in the Activity Bar and start chatting.
Supported Providers
| Provider |
Chat |
Embeddings |
Notes |
| OpenAI |
✓ |
✓ |
|
| Mistral |
✓ |
✓ |
Default |
| Anthropic |
✓ |
— |
Chat only |
| Google Gemini |
✓ |
✓ |
|
| Ollama (local) |
✓ |
✓ |
Fully offline — see below |
Mix and match — use Anthropic for chat and Mistral for embeddings, for example.
Changing embedding provider or model requires a re-index. Nexus will warn you and disable chat until the new index is ready.
Using Ollama (local, no API key required)
- Install Ollama and pull a chat model and an embedding model:
ollama pull mistral          # or llama3.1, qwen2.5, etc.
ollama pull nomic-embed-text # recommended embedding model for Ollama
- In VS Code settings (
Code → Settings → Extensions → Nexus AI):
nexus.chatProvider → ollamanexus.chatModel → mistral (or whichever you pulled)nexus.embeddingProvider → ollamanexus.embeddingModel → nomic-embed-textnexus.ollamaBaseUrl → http://localhost:11434 (default — change if Ollama runs elsewhere)
- No API key needed — skip the
Nexus: Set API Key step entirely.
- Run
Nexus: Index Workspace and start chatting.
Settings
| Setting |
Default |
Description |
nexus.chatProvider |
mistral |
LLM provider for chat |
nexus.chatModel |
mistral-small-latest |
Chat model name |
nexus.embeddingProvider |
mistral |
Embedding provider |
nexus.embeddingModel |
mistral-embed |
Embedding model name |
nexus.hopDepth |
1 |
Graph traversal depth (higher = more context, slower) |
nexus.maxNodes |
15 |
Max context nodes per query |
nexus.ollamaBaseUrl |
http://localhost:11434 |
Ollama base URL |
nexus.backendUrl |
http://localhost:8000 |
Backend URL — override only when running the backend manually |
Commands
| Command |
Description |
Nexus: Index Workspace |
Build or refresh the code index |
Nexus: Clear Index |
Remove the index for the current workspace |
Nexus: Setup — Configure API Key |
Guided setup flow to configure your API key |
Nexus: Set API Key (choose provider) |
Store an API key for a specific provider |
Nexus: Clear API Key |
Remove a stored API key |
Nexus: Open Settings |
Open Nexus extension settings directly |
Source & License

